Running LLMs Locally: How to Pick the Right Tool and Model for Your Machine
A practical guide for getting your first local model running — and choosing one that actually fits the hardware you already own.
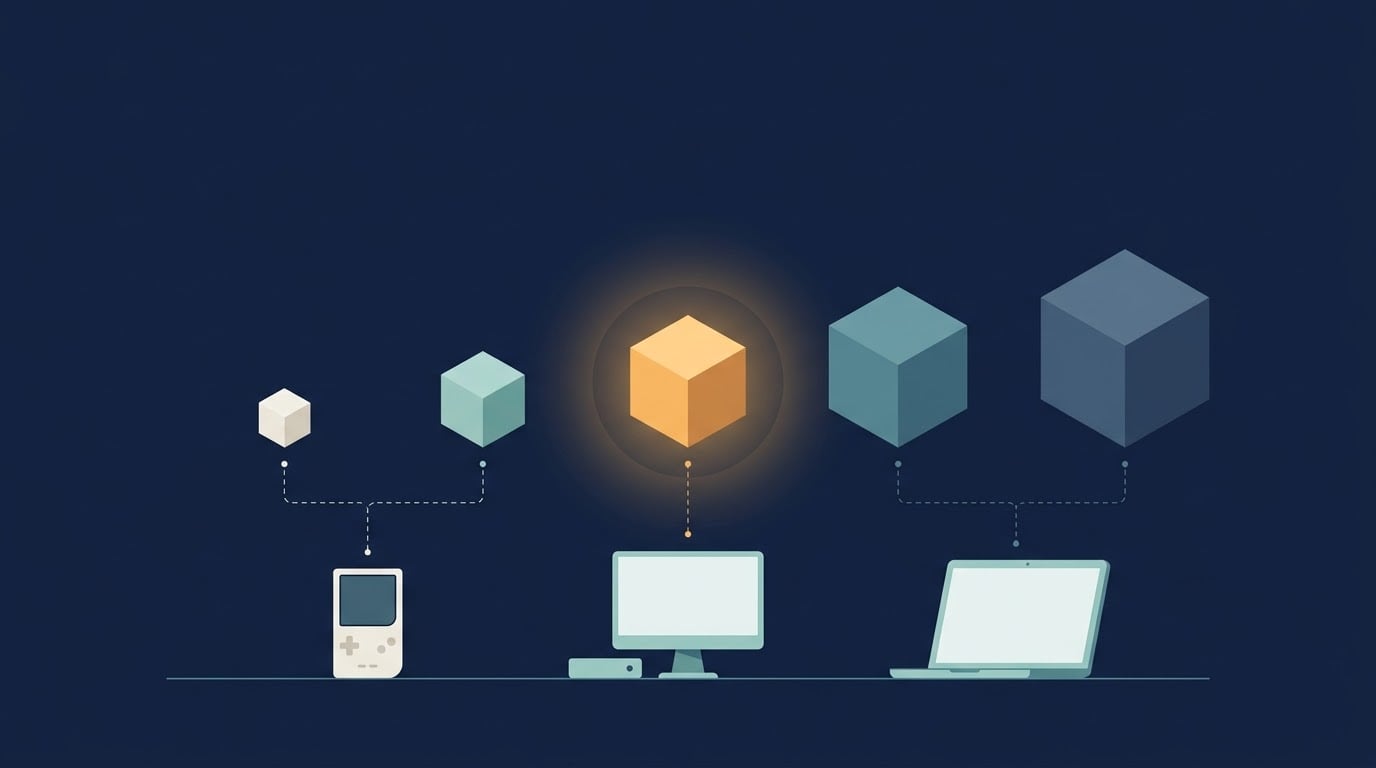
A practical guide for getting your first local model running — and choosing one that actually fits the hardware you already own.
How to run specialized agents that coordinate on a shared task — entirely on local hardware
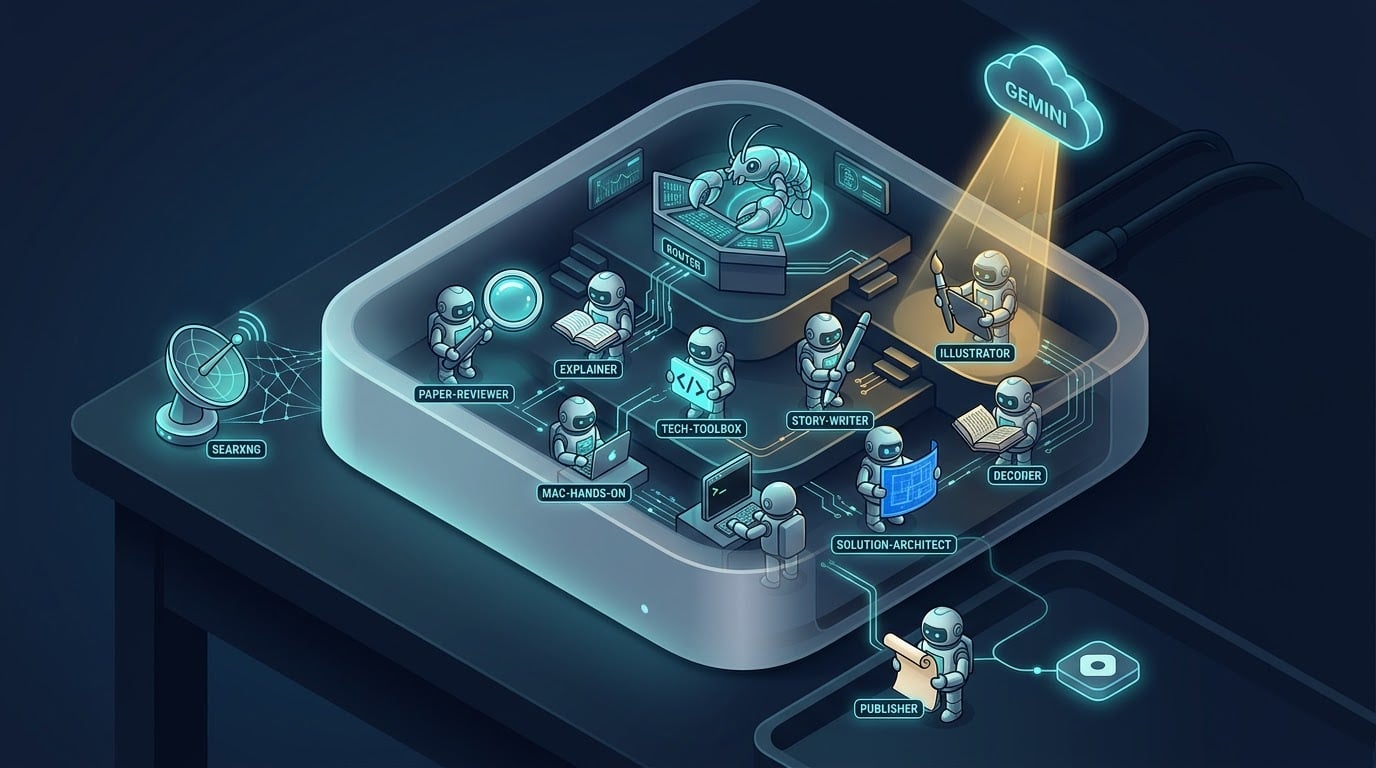
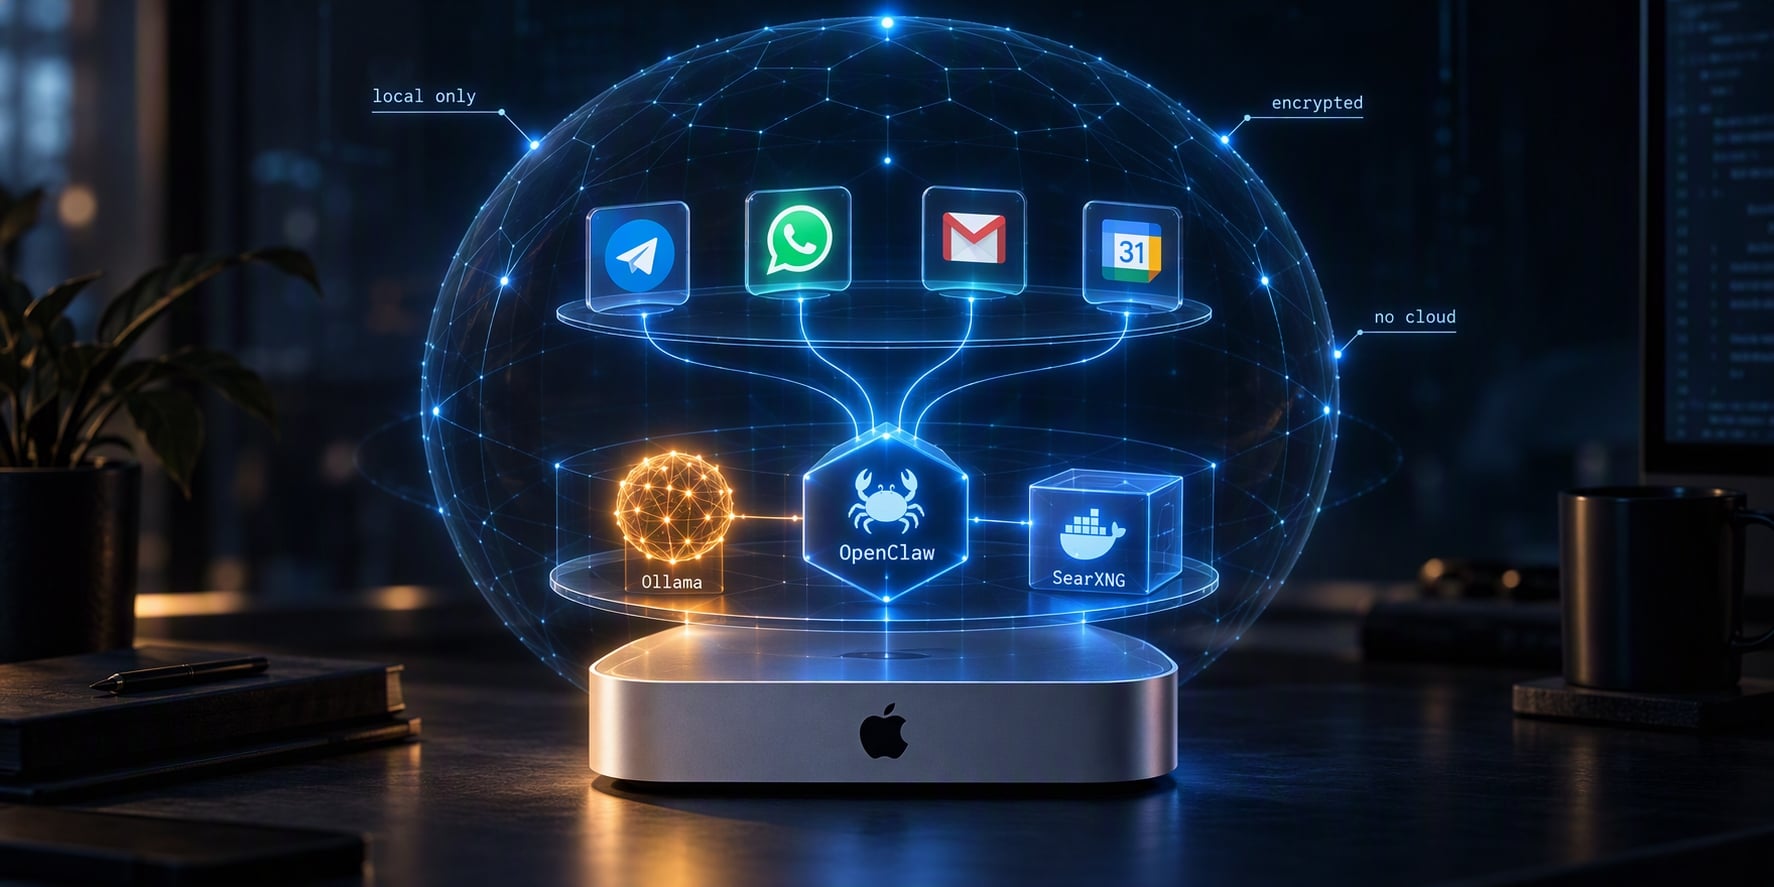
A Mac mini running Ollama and OpenClaw is a capable local AI stack. The missing piece has always been access to frontier-scale models without needing a GPU cluster. NVIDIA's free API tier on build.nvi
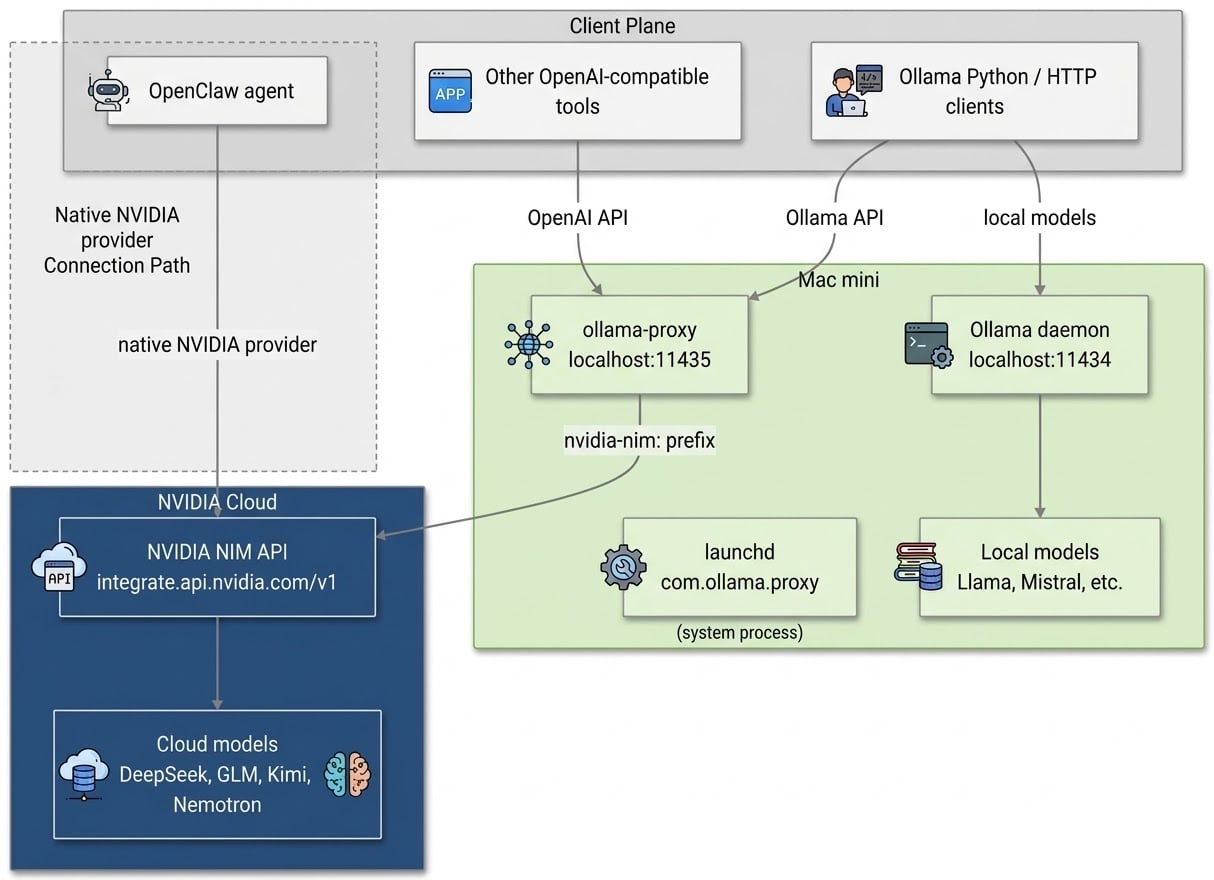
A Mac mini is not a toy. Even the base model can run 8B-parameter models at conversational speeds, host a persistent AI agent, and handle real work without sending a single byte to the cloud. Higher c