TencentDB Agent Memory: A Local-First Memory Layer for AI Agents
A layered semantic pyramid that makes agent memory inspectable, traceable, and local-first
Every agent developer knows the feeling. You start a new session, and your agent has amnesia. You re-explain your stack, your preferences, your project conventions. The context you painstakingly built yesterday is gone.
Most memory systems try to solve this by compressing conversation history into a vector pile. Retrieval becomes a black box: when recall goes wrong, you're guessing why.
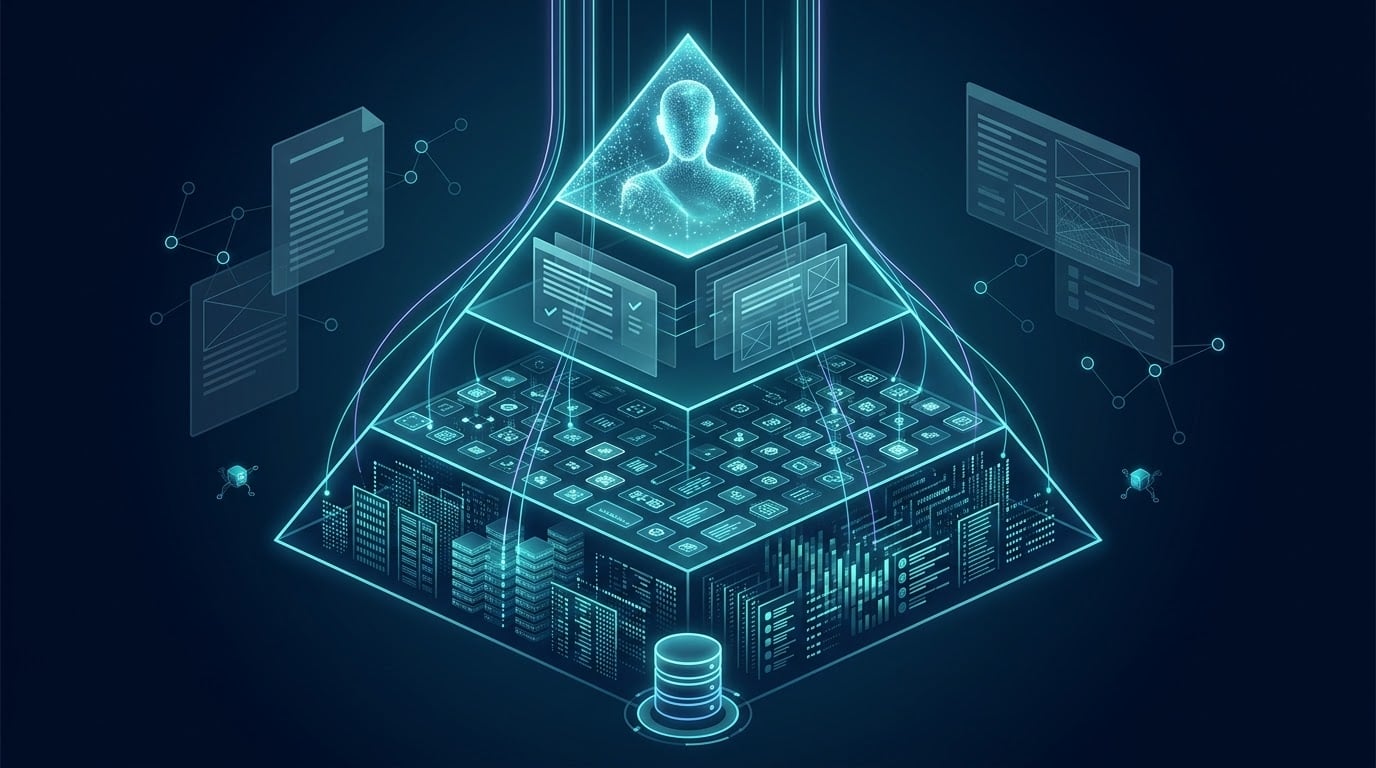
TencentDB Agent Memory takes a different approach. Open-sourced by Tencent Cloud in May 2026 under the MIT license, it builds memory as a layered semantic pyramid — every layer readable Markdown, every conclusion traceable back to its raw source. The project crossed 20,000 GitHub stars in 90 days and reached No. 1 on GitHub Trending multiple times.
The Problem with Flat Vector Memory
The standard approach today is straightforward: dump conversation history into a vector database, embed everything, and retrieve the top-K most similar chunks at inference time.
This works for short conversations. It breaks down in long-running agent workflows.
Tencent's team identifies three core issues:
Cross-session fracture. Code conventions confirmed yesterday are forgotten today.
Fact-preference conflation. "I use TypeScript" and "check the weather" get treated with equal weight.
Context bloat. The longer the task, the more history gets stuffed into the context window. Token costs climb, and model attention degrades.
The deeper issue is that flat vector memory makes recall opaque. When retrieval goes wrong — pulling in stale state, conflating old and new decisions — you have no way to trace why.
The Architecture: A Semantic Pyramid
TencentDB Agent Memory organizes long-term memory into four tiers, each with a distinct role:
| Layer | What It Stores | Format |
|---|---|---|
| L0 Conversation | Raw dialogue and tool-call logs, full fidelity | Complete records |
| L1 Atom | Extracted facts, preferences, constraints — each with source links | Structured atomic facts |
| L2 Scenario | Aggregated knowledge blocks per task/project | Markdown files |
| L3 Persona | Stable long-term user profile and team norms | Key-value pairs |
The key design principle: nothing is lossy-compressed. Every layer is readable Markdown. When the agent needs proof for a conclusion, it can drill back through node_id links to the exact raw log at L0.
This is what Tencent calls a white-box traceable memory system — you can follow the chain from a stable persona trait down to the specific conversation where it originated.
Short-Term Memory: Symbolic, Not Stuffed
For within-session context management, the system uses a symbolic short-term memory layer. Current task state is encoded as a Mermaid graph in the agent's context — a lightweight, structured representation of what's happening right now.
Verbose tool logs get offloaded to disk. When the agent needs them, it drills back via node IDs. The context window stays clean; the full history stays accessible.
Benchmark Results
Tencent reports significant improvements across multiple benchmarks. All figures are vendor-reported and have not yet been independently verified at scale.
| Benchmark | Before | After | Change |
|---|---|---|---|
| PersonaMem accuracy | 48% | 76% | +59% |
| WideSearch pass rate | 33% | 50% | +51.52% (relative) |
| WideSearch token usage | 221.31M | 85.64M | −61.38% |
| SWE-bench pass rate | 58.4% | 64.2% | +9.93% |
| SWE-bench token usage | 3,474.1M | 2,375.4M | −33.09% |
Data from Tencent Cloud's official benchmarks.
The PersonaMem result is the most striking: accuracy nearly doubling while token consumption drops by more than half. The system achieves this by not injecting raw history into context — instead, it retrieves structured L1/L2/L3 representations that are denser and more relevant than flat text chunks.
One caveat worth noting: these benchmarks measure performance with the system integrated as an OpenClaw plugin. Results may vary across different agent frameworks and task types.
Multi-Agent and Team Memory
The most recent major update — Team Memory, launched in August 2026 — extends the system from individual use to team collaboration.
The core idea: when team members work alongside agents, the conversations, documents, code, and workflows they produce should become shared memory assets, not isolated session histories.
Team Memory introduces four types of assets:
Chat Memory: Historical agent conversations, organized for retrieval
LLM-Wiki: Project documents converted into queryable structured pages
Code Graph: Code repositories parsed into symbol relationships and call paths
Skill: Successfully completed workflows distilled into reusable task patterns
These assets are dynamically assembled based on agent role. A bug-fixing agent prioritizes Code Graph and past troubleshooting Skills. A requirements-analysis agent loads the project wiki and previous discussions.
Team Memory API: Scoping and Sharing
The V3 API introduces a team_id dimension for team-level memory isolation and sharing. The scoping chain runs from largest to smallest: team_id → user_id → agent_id → session_id.
This means the same interface can perform team-level memory sharing or session-level precise retrieval, depending on which dimensions you specify.
DeepSeek Harness Integration
TencentDB Agent Memory has been adapted for DeepSeek Harness (DSH). The integration works via a Memory Proxy that sits between Harness and the model service — no modifications to the Agent Core or execution loop are required.
For DSH users, this adds four capabilities: long-term memory across sessions, Skill sedimentation and sharing, Wiki and CodeGraph retrieval, and cross-IDE asset sharing with permission controls.
Relationship to Vector Databases
A common misconception is that this project replaces vector databases. That's not accurate.
TencentDB Agent Memory's local/free version runs on plain SQLite with a WASM build of FAISS for local retrieval — no external vector database required. This is a deliberate design choice for individual developers and small teams who don't want to run separate infrastructure just to give an agent memory.
But the enterprise/pro version still uses Tencent Cloud VectorDB (TCVDB) as its indexing layer. In Tencent's own testing, the system handles tens of millions of conversation memories with sub-5ms end-to-end retrieval latency.
The architecture is complementary, not competitive. Vector databases solve large-scale retrieval infrastructure — multi-tenancy, high concurrency, governance, backup. Agent Memory solves session-context organization and memory lifecycle management. They operate at different layers of the stack.
Getting Started
Installation is designed to be straightforward:
git clone https://github.com/TencentCloud/TencentDB-Agent-Memory.git
cd TencentDB-Agent-Memory/deploy/global-images
cp .env.example .env
# Fill in two sets of LLM parameters (memory group + proxy group)
./start-all.sh