Unlimited OCR: A 3B Local Model for Long-Context PDF Parsing
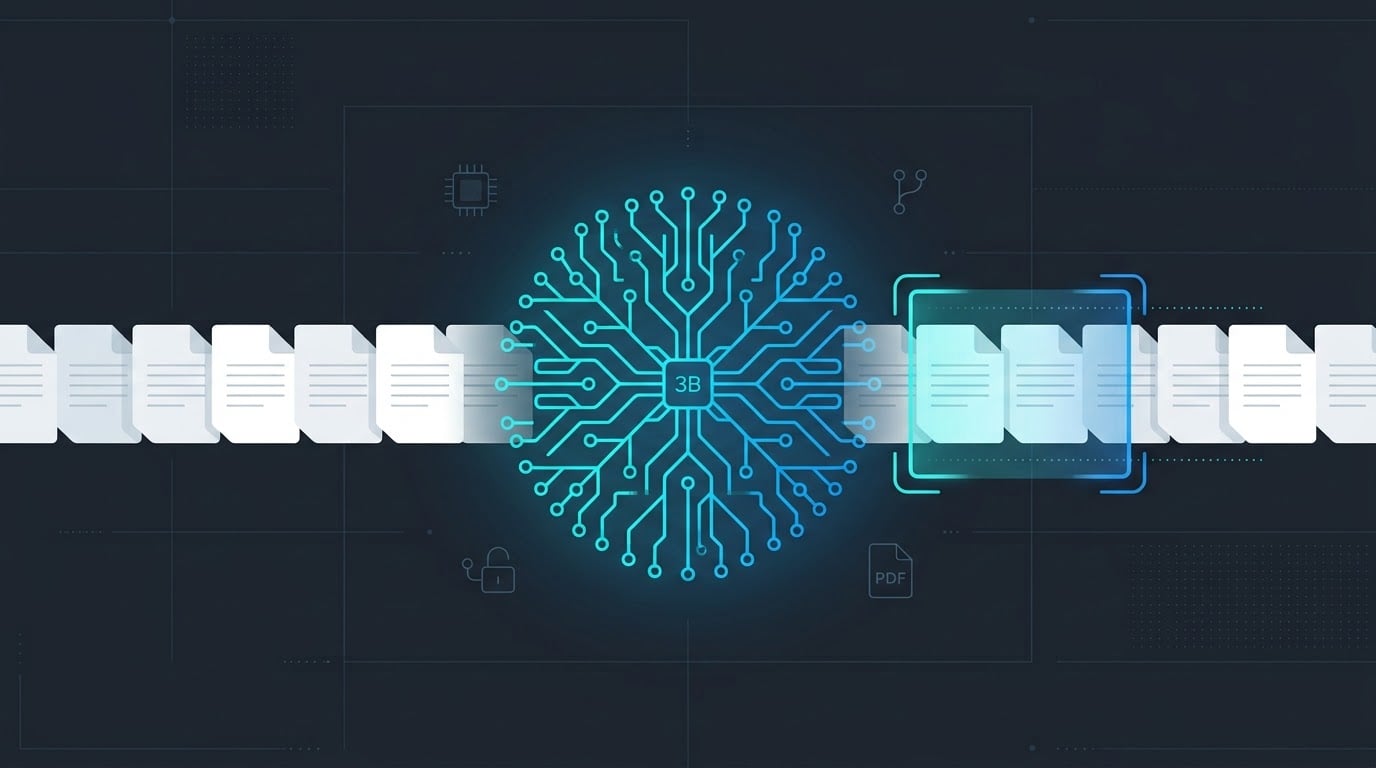
Baidu has open-sourced a document parsing model called Unlimited OCR. It is a 3B-parameter model designed to run locally. The main difference from many existing OCR tools is that it processes long PDFs in a single pass instead of splitting them into pages.
Most OCR pipelines treat each page independently. That works for simple extraction, but it can lose cross-page structure and context. Unlimited OCR is positioned around that problem: parse the whole document continuously.
What was released
Unlimited OCR was released on June 22, 2026. It is available on GitHub and Hugging Face under an MIT license. The model is also available on ModelScope and Baidu Cloud. The release states support for multiple runtimes, including Transformers, vLLM, SGLang, Docker, Ollama, and llama.cpp.
The model has 3 billion total parameters but activates only about 570 million during inference. It is described as an effort to push DeepSeek OCR one step further.
How it works
The core technical contribution is called Reference Sliding Window Attention (R-SWA). The model replaces all attention layers in the decoder with R-SWA.
In standard transformer decoding, the KV cache grows as the output sequence lengthens. This increases memory consumption and progressively slows down generation. R-SWA addresses this by maintaining a constant KV cache throughout the entire decoding process. This allows the model to transcribe dozens of pages in a single forward pass under a standard maximum length of 32K.
The paper notes that R-SWA is a general-purpose parsing attention mechanism and could be applicable beyond OCR to tasks such as ASR and translation.
Benchmarks
On OmniDocBench v1.5, Unlimited OCR scored 93.23% overall, which the release describes as end-to-end SOTA, outperforming DeepSeek OCR by 6 percentage points. The release also reports 93.92% on OmniDocBench v1.6.
OmniDocBench is a benchmark that evaluates document parsing across nine document sources, including academic papers, textbooks, handwritten notes, and densely typeset newspapers. It supports multi-level evaluation using 19 layout categories and 15 attribute labels.
The release reports an error rate under 0.11 past 40 pages.
Note on benchmark versions: v1.5 and v1.6 are different benchmark versions. OmniDocBench v1.6 includes 1,651 pages and adds five acquisition conditions: scanning, warping, screen photography, uneven illumination, and skew. Cross-version comparisons should be treated as directional rather than absolute.
Cost comparison
Cloud OCR services price at roughly $1.50 per 1,000 pages for basic text extraction. AWS Textract's DetectDocumentText tier is $1.50 per 1,000 pages for the first million. Structured extraction tiers rise significantly: AnalyzeDocument with Forms costs $50 per 1,000 pages, Tables adds $15 per 1,000, and combining all three reaches $65 per 1,000 pages.
Azure Document Intelligence's Read model (OCR only) is approximately $1.50 per 1,000 pages. Layout and prebuilt models cost around $10.00 per 1,000 pages, and custom models are billed at approximately $30.00 per 1,000 pages.
Google Cloud Vision's text detection is also $1.50 per 1,000 units after the first 1,000 free units per month.
Unlimited OCR does not have a per-page API fee. It runs on local hardware, so the real cost is hardware, electricity, and maintenance.
Limitations and open questions
Hardware requirements are not clearly stated in the release materials. VRAM and throughput on consumer hardware will matter for long documents.
Accuracy on tables, formulas, handwriting, and low-quality scans needs independent testing. The benchmark covers these categories, but the reported scores are from the release itself.
Language coverage details need verification. The model card lists "multilingual" but does not specify which languages.
The 32K context window is large, but very long PDFs may still require chunking.
Local inference shifts cost from API fees to hardware and electricity.
The 93.23% and 93.92% figures come from the release materials. Independent reproductions would strengthen confidence in these numbers.
Conclusion
Unlimited OCR is notable because it targets long-context document parsing in a relatively small 3B model that can run locally. The R-SWA mechanism addresses a real bottleneck in long-sequence decoding: growing memory consumption and generation slowdown. If the reported results hold up in independent tests, it could simplify OCR pipelines that currently depend on page-by-page processing or cloud APIs.
References
Official sources
Baidu. "Unlimited OCR Works: Welcome the Era of One-shot Long-horizon Parsing." GitHub repository. https://github.com/baidu/Unlimited-OCR
Baidu. "Unlimited-OCR." Hugging Face model card. https://huggingface.co/baidu/Unlimited-OCR
Yin, Youyang, et al. "Unlimited OCR Works." arXiv:2606.23050, June 22, 2026. https://arxiv.org/abs/2606.23050
Baidu. "Unlimited-OCR." ModelScope. https://modelscope.cn/models/PaddlePaddle/Unlimited-OCR
Benchmark
"OmniDocBench: Benchmarking Diverse PDF Document Parsing with Comprehensive Annotations." IEEE Xplore, August 13, 2025. https://ieeexplore.ieee.org/abstract/document/11091844
Dataset and code: https://github.com/opendatalab/OmniDocBench
Cloud OCR pricing
"Google Vision vs AWS Textract vs Azure: Cloud OCR Comparison 2026." ImageToTable, June 30, 2026. https://imagetotable.ai/blog/google-vs-aws-vs-azure-ocr-2026
"Azure Document Intelligence pricing." Microsoft Q&A, July 2, 2026. https://learn.microsoft.com/en-au/answers/questions/5927427/azure-document-intelligence-pricing
Community forks and additional references
"Unlimited-OCR-Universal." Hugging Face (Apple Silicon/MPS fork). https://huggingface.co/sabafallah/Unlimited-OCR-Universal
"unlimited-ocr-max." PyPI package for OpenAI-compatible serving. https://pypi.org/project/unlimited-ocr-max
Baidu Cloud deployment documentation. https://cloud.baidu.com/doc/OCR/s/fmr1p39gb
Note on citations: The release date, GitHub repository, Hugging Face model card, arXiv paper, OmniDocBench paper, and cloud pricing pages cited above are the primary sources. The 93.23% and 93.92% figures and the 0.11 error rate come from the release materials and should be treated as vendor-reported until independently reproduced.