How a Laptop Learned to Run a Giant: A Plain-English Guide to Local vs Cloud AI
Quantization and offloading, the new shape of AI models, the real cost of local versus cloud, and why the future is hybrid
New to the jargon? Start with the glossary →
This guide brings together four essays from the Big Models, Small Machines series. Part 1 explains the tricks that let a laptop run a giant model. Part 2 explains why model size stopped being the number that matters. Part 3 does the real cost maths of local versus cloud. Part 4 explains why the answer is usually both.
Part 1 — How a Laptop Learned to Run a Giant
A 70-billion-parameter model is roughly 140 GB of data. A mid-range gaming laptop has between 8 and 16 GB of video memory.
That's like trying to pour a swimming pool into a teacup. It shouldn't fit. So how is it running?
The answer is that we stopped trying to force the whole model into memory at once. Instead, we shrink it, we share the load, and we only use the parts we actually need. Here are the three tricks that make it possible.
Trick 1: Shrinking the Model
The first problem is pure size. You can't fit 140 GB into an 8 GB space. So we make the model smaller.
Quantization is the biggest lever. Think of it like a high-resolution photo. The original model uses 16-bit precision (called FP16), where every single parameter takes up 2 bytes of memory. That's the "high-res" version. Quantization drops that down to 8-bit (INT8), then 4-bit (INT4). At INT4, every parameter takes just 0.5 bytes.
That 140 GB model suddenly drops to around 35 GB. You lose a little bit of quality—the photo gets slightly blurrier—but you save an enormous amount of memory.
Pruning is the second lever. Researchers look at the model's billions of parameters and find the ones that aren't pulling their weight. They zero them out, effectively deleting them. It's like trimming dead branches off a tree so the rest can breathe.
Knowledge distillation is the third. Instead of compressing a big model, you train a small model to copy a big one. The small model learns from the big model's answers and reasoning, like an apprentice learning from a master. You end up with a model a fraction of the size, carrying a surprising amount of the original's capability.
Trick 2: Sharing the Load
Shrinking helps, but a 35 GB compressed model still doesn't fit comfortably into 16 GB of video memory. So we use everything the computer has.
Unified memory changed the game on Apple Silicon. In a traditional PC, the CPU has its own RAM, and the GPU has its own VRAM. Moving data between them is slow. Apple's M-series chips use a single pool of memory shared by both the CPU and the GPU. A MacBook Pro with 128 GB of unified memory can hold a ~65B model comfortably—no copying required.
CPU offloading is the PC equivalent. Instead of demanding that the entire model live on the graphics card, tools like llama.cpp split the model up. The "hot" layers that are needed right now stay on the GPU. The rest sit in system RAM, and the CPU handles them.
Is it slower than pure GPU inference? Yes. But it's a thousand times better than not running at all.
Trick 3: Doing Less Work
The final trick is architectural. Modern models are simply smarter about how they use themselves.
Mixture of Experts (MoE) is the biggest shift. Instead of a monolithic model that uses all 70 billion parameters for every single question, an MoE model is made of many smaller specialist teams. When a question comes in, a router sends it to just a few of those experts—maybe 8 to 10 billion parameters' worth. The model is huge on paper, but computationally cheap in practice. Examples like Mixtral, Qwen2.5-MoE, and Grok use this to deliver massive capability without massive compute costs.
Sparse attention reduces the memory and compute required for long contexts. Instead of forcing the model to look at every single word it has ever seen, sparse attention focuses only on the relevant parts. It cuts the math down drastically.
And then there's just better design. Models like Llama 3 and Qwen 2.5 are simply more parameter-efficient than their predecessors. A smaller model today beats a bigger model from two years ago.
The Reality Check
So what does this actually look like on your desk?
If you have a Mac Mini (M-series) with 32 GB of RAM, you can run Qwen2.5-14B or Llama-3-8B comfortably at INT4. You might even squeeze in a 32B model if you're aggressive with quantization and don't have much else open.
If you have a MacBook Pro with 64 GB or 128 GB of unified memory, the world opens up. You can run a 70B model at INT4. It's slow—roughly 5-10 tokens per second—but it runs, completely offline, no API calls needed. We're talking batch processing and careful prompting, not instant chat.
There is a tradeoff. Larger models mean slower inference, more heat, and louder fans. But here's the part that surprises most people.
Training an AI model requires massive, sustained compute. It's like running a marathon at sprint speed for weeks. But inference—just using the model to get an answer—doesn't need that same intensity. You're reading a huge matrix multiplication table, not calculating it from scratch.
That's why a laptop can do this. It's not performing miracles. It's just reading the answer, one compressed piece at a time.
Part 2 — The New Shape of AI Models
Here's a riddle. Two AI models are released on the same day. Both have 70 billion parameters. One runs comfortably on a laptop. The other needs a data center. On paper, they are the same size. They are not the same machine.
That gap—between what a model is on paper and what it does when it runs—is the story of this essay. The parameter race didn't just slow down. It split into different questions entirely.
Size was always a proxy
In Essay 1, we talked about why "bigger equals smarter" broke. The short version: parameter count was never a direct measure of intelligence. It was a rough proxy, and for a while, that proxy worked well enough.
But it was always a proxy for something else—the model's capacity to learn patterns. More parameters meant more room to store what it learned. That's it. It said nothing about how the model used that space.
Two models with the same parameter count can store their knowledge in completely different ways. One might use every single parameter for every question. The other might use a small fraction, on purpose, every time. Same number on the box. Different machine inside.
That's what changed.
The model that doesn't use all of itself
Most people imagine an AI model like a brain where every neuron fires for every thought. An MoE model doesn't work that way. Here's what it actually is: instead of one giant model where every parameter fires for every question, it's made of many smaller specialist sub-networks—the "experts." A router sits on top. When a question comes in, the router decides which experts are best suited to answer. Only those experts wake up. The rest stay dormant.
Think of it like a hospital. You don't need every doctor, nurse, and specialist in the building to look at a sprained ankle. You need the triage nurse and the orthopedic specialist. The rest of the hospital is there, ready if needed, but they're not all crowding into the room.
Mixtral 8x7B illustrates this perfectly. It has roughly 47 billion total parameters. But for any given token, it activates only around 13 billion of them. That's the compute cost of a 13B model, with the capability that comes from something much larger.
The same pattern appears at larger scales. DeepSeek-V3 has 671 billion total parameters. Per token, it activates only about 37 billion. That's the compute footprint of a mid-sized model, running on a system that's 18 times bigger on paper.
Here's the catch that's easy to miss. MoE reduces compute, not memory. The full 671 billion parameters still have to be loaded — all of them, into memory, before the model can answer a single question. The architecture changes what runs per token. It doesn't change what has to live in RAM. That's why a 671B MoE model still needs serious hardware. Quantization is what makes it fit. MoE is what makes it fast.
The number that actually matters
This is where the vocabulary splits. We now have to distinguish between two things that used to be the same:
Total parameters — the number on the box. How much the model can know.
Active parameters — how much the model uses per answer. How much compute it actually spends.
The first number tells you about capability. The second tells you about cost. And the second is the one you'll feel when you're actually running the thing.
A 671B model with 37B active parameters is not the same as a 37B model. It has more depth to draw from. But it runs at roughly the speed and cost of a 37B model, which is why it fits on hardware that couldn't dream of running a dense 671B model.
This is what people mean when they say MoE "decouples size from cost." It's the same reason a laptop can run a model that looks like it should need a data center.
This connects directly to what we saw in Essay 2. MoE is one piece of the puzzle — it's also what lets a 671B model fit on hardware that couldn't run a dense version at all. Combined with quantization and unified memory, "fits on my machine" becomes a real thing.
Small specialists vs. big generalists
There's a second shift happening alongside MoE. Small models got much better — but not because small is inherently better. They got better because they're being taught by larger models.
The technique is distillation. A large teacher model generates answers, reasoning chains, and corrections. A small student model learns from those outputs instead of from raw data. The student doesn't rediscover knowledge from scratch. It copies what the teacher already figured out, at a fraction of the size.
That's why a well-trained 8B model today can outperform a 70B model from two years ago. It's not that the architecture got smarter. It's that the training recipe changed. The student is learning from a better teacher than the older model ever had.
Look at Granite 3.2 8B. IBM trained it to match or exceed models several times its size on math and reasoning benchmarks. Look at Llama 3 8B, which beats the original Llama 2 70B on most tasks. The pattern is everywhere.
But there's a limit worth naming. Small models are excellent at reasoning, style, and structured tasks. They are not as good at factual recall for long-tail queries. Ask a small model about an obscure historical figure, a niche technical detail, or a specific legal precedent, and it's more likely to hallucinate than a larger model that actually stored the fact. Knowledge has to live somewhere, and compression has a ceiling.
The honest version of the story: small models aren't smaller versions of big models. They're differently trained. They got better at some things, and they still can't do others.
Thinking longer, not bigger
The third shift is the strangest one. Some models now get smarter by thinking longer, not by being bigger.
Instead of answering immediately, these models produce a chain of reasoning before giving their final response. They check their work. They try approaches and abandon them. They take more time—and in many cases, the extra time translates directly into better answers.
Models like OpenAI's o3 and DeepSeek-R1 don't just answer your question—they think through it first, producing a chain of reasoning before committing to an answer. You give them more time (more tokens), and they beat larger models that fire off instant responses. Extra compute at inference time is the new parameter count arms race.
Think of it like the difference between a quick answer and a considered one. If you ask someone a hard question, the immediate reply and the reply after thirty seconds of thought are not the same quality. Models learned this too.
The practical implication: "how smart is this model?" now depends partly on how long you let it think. That's not a question you can answer by looking at the parameter count at all.
There's a tax here, though, and it's worth naming. Thinking longer means waiting longer. For a research task, a batch job, or a careful analysis you'll read once — fine. For a voice assistant, a real-time coding tool, or anything interactive, that latency is fatal.
The industry is converging on the idea of two modes. A fast, intuitive mode for quick tasks. A slow, deliberate mode for hard ones. The best systems switch between them on demand. Neither replaces the other.
The new scorecard
Put those three shifts together—MoE, better small models, test-time compute—and the old scorecard doesn't work anymore.
Parameter count was never enough, but now it's barely a starting point. The questions that actually matter when you're choosing a model are different. You want to know how many parameters it actually uses per answer, not just how many it has. You want to know how well it was trained and on what data. You want to know how many tokens per second it will give you on your hardware, how much it costs per answer, per day, per month, and whether it fits on the machine you already have.
That's a more complicated set of questions than "how big is it?" But it's a more honest one. And every model released in the last two years has been designed with at least one of those questions in mind.
The parameter race didn't disappear. It fragmented. The old race was one-dimensional: who can build the biggest model. The new race is a triangle — capacity, latency, and memory. You can optimize two. The third will always demand a tax. There is no single number that captures a model anymore. There never really was.
Written in early 2026. Model examples reflect the landscape at that time.
Part 3 — Who Actually Saves Money?
"Local AI is free."
You'll see that line in forum threads, in YouTube comments, in the pitch for every new tool that runs on your own machine. It sounds true. You download a model, you run it, and no bill arrives at the end of the month.
But it's not free. It's prepaid. And "prepaid" is a very different thing than "free."
The bill doesn't disappear — it just arrives earlier, in one lump, before you've generated a single token. And whether that prepayment actually saves you money depends entirely on what you're doing, how often, and how sensitive your data is.
This essay is about figuring out which side of that line you're on.
The Real Bill: What Local Actually Costs
Let's start with the hardware. You need a machine capable of running the models you care about. For a 27B model at 4-bit quantization, that means a computer with 32 to 64 GB of unified memory. A capable laptop or small desktop in that range costs somewhere between $1,500 and $2,500. Let's call it $2,000 as a working number.
That's the upfront cost. It's real, and it's large.
Then there's electricity. A machine running inference under sustained load draws somewhere between 30 and 80 watts, depending on the chip and how hard you push it. At average residential electricity rates, running that machine four hours a day costs roughly $3 to $7 per month. It's not nothing, but it's small.
Then there's time. Setup, maintenance, troubleshooting, keeping models up to date, dealing with the occasional broken dependency. If you value your time at even a modest hourly rate, the first month of local AI costs more in time than in hardware.
That's the honest picture. Local AI is a capital expense followed by a small operational expense. The big number comes first.
The Real Bill: What Cloud Actually Costs
Cloud AI flips the structure. There's no upfront cost. You pay per token, or you pay a flat subscription fee.
Take a representative example. A frontier cloud model — the kind you'd use for the hardest tasks — charges roughly $2.50 per million input tokens and $10 per million output tokens. A lighter model might cost a fraction of that. A monthly subscription to a chat interface typically runs $20.
The cloud pricing has three properties worth noticing:
It scales with usage. The more you use, the more you pay. There's no ceiling and no floor. A heavy month costs more than a light one.
It's invisible until it isn't. A $20 subscription feels small. A $200 API bill at the end of a heavy month feels very different.
It requires the network. Every request leaves your machine, hits a server, and comes back. That's usually fine. Sometimes it isn't.
So cloud AI is an operational expense with no capital cost. The small number comes first, and it never stops coming.
The Break-Even Point
Now the interesting part. When does the local prepayment start paying for itself?
The math is simpler than it looks. You're comparing a one-time cost plus a small monthly cost against a monthly cost that scales with usage.
Take the $2,000 machine. Add $5 per month for electricity. Call it $2,005 in year one, then $60 per year after that.
Now compare it to two cloud scenarios:
Light user. Someone who uses AI casually, maybe a few queries a day. A $20 monthly subscription covers it. That's $240 per year. Break-even against local hardware happens after roughly 8 to 10 years. Cloud wins.
Heavy user. Someone generating millions of tokens per month — running agents, batch jobs, or sustained development work. At $50 to $100 per month in API costs, break-even against local hardware happens in 20 to 40 months. Local starts to win.
Very heavy user. Someone running overnight batch jobs or continuous agents. Cloud costs can climb into hundreds of dollars per month. Break-even happens in under a year. Local wins by a wide margin.
The pattern is clear: the more you use it, the more local hardware pays for itself. Cloud is cheaper for occasional use. Local is cheaper for sustained use.
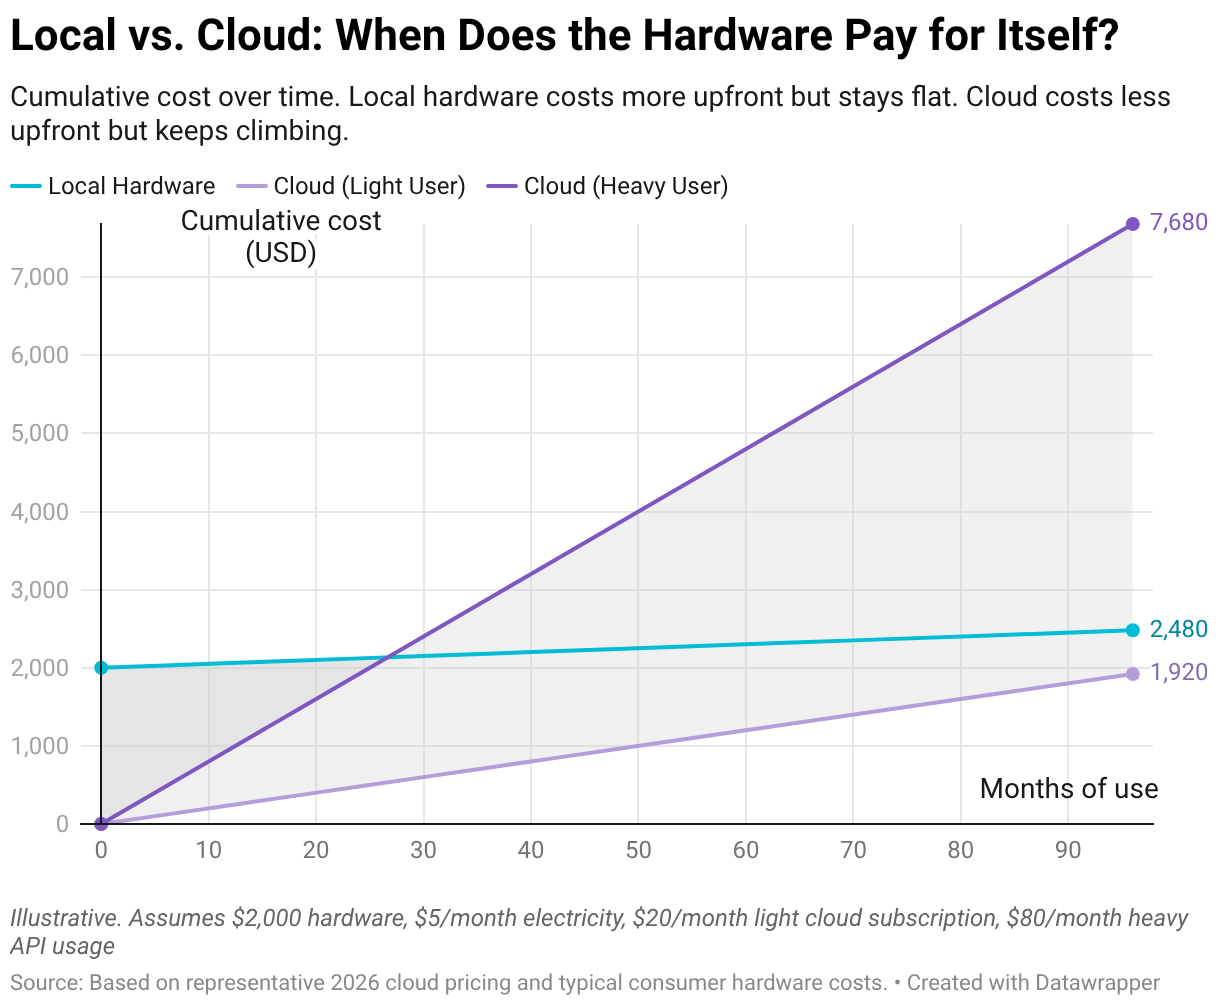
Illustrative. Actual costs depend on hardware prices, electricity rates, model choice, and usage patterns.
When Local Wins, and When It Doesn't
Cost is only one axis. Privacy, latency, and dependency matter too. Here's how the decision breaks down by task.
Sensitive data — medical records, legal documents, personal journals, internal company material. Local wins. Full stop. The moment data leaves your machine, you've lost control of it. No cloud provider, no matter how trustworthy, changes that. If the data is sensitive, local is the only real option.
Overnight batch jobs — processing thousands of documents, summarizing archives, running evaluations. Local wins. Latency doesn't matter here. You're not waiting for the answer. The model can churn through the work at 5 tokens per second, and nobody cares. Cloud costs scale with volume here, which means the bill grows fast.
Offline work — on a plane, in a remote area, anywhere the network is unreliable. Local wins. Cloud is simply unavailable.
Frontier capability — the hardest reasoning tasks, the most complex coding, the newest and best models. Cloud wins. The best models are still too large to run locally on consumer hardware, and they may stay that way for a while. If you need the best possible answer, you pay for it.
Real-time conversation — a chat interface you use throughout the day. Cloud usually wins. Cloud inference is fast. Local inference, on a 27B model at 4-bit, runs at maybe 10 to 20 tokens per second. That's fine for reading but slow for real-time back-and-forth.
One-off experiments — trying a new model, testing a prompt idea, playing around. Cloud wins. You don't want to download 20 GB and configure a runtime just to try something once.
Long-term daily use, any task. Local starts to win. The longer your horizon, the more the math tilts.
The Quiet Costs Nobody Talks About
There are costs that don't show up in the spreadsheet but show up in daily life.
Fan noise. Running a 27B model at full tilt on a laptop means the fans spin up. If you work in a shared space, this matters more than the electricity bill.
Slow first token. Local inference has a longer warm-up. The model loads from disk, the context gets processed, and only then does it start generating. Cloud models hide this latency behind fast servers.
Model drift. The models you can run locally are not the same as the ones you can access in the cloud. When a new frontier model drops, you can't run it on your machine the day it's released. You wait for a smaller, distilled, or quantized version to appear. That gap is a real cost.
Maintenance drift. Local setups break. Dependencies change. A model that worked last month stops working this month. Cloud, for all its flaws, is someone else's problem to maintain.
None of these costs are deal-breakers. But they're real, and anyone considering a local setup should account for them.
The Question That Actually Matters
So which is cheaper — local or cloud?
The honest answer is that this was never a binary choice. The right question isn't "which one is cheaper?" It's "for this task, at this frequency, with this data, which one is the better fit?"
For sensitive data, offline work, and sustained heavy use, local wins. For frontier capability, real-time interaction, and occasional use, cloud wins. For most people, most of the time, the answer is both — and the interesting part is figuring out where the line is.
That line is not a wall. It's a dial.
And that dial is exactly what Part 4 is about.
Sources: Cloud pricing based on representative public rates for a frontier model as of 2026. Hardware pricing based on typical consumer configurations. Electricity costs based on average residential rates.
Part 4 — The Future Is Both
Most AI systems today pick a side. They run entirely local or entirely cloud. That's a design choice, not a law of nature.
The choice made sense when local and cloud were genuinely different tools. Local was private but weak. Cloud was capable but exposed. Picking one meant accepting its weakness. That trade-off has narrowed.
Local models are now good enough for most queries. Cloud models are still better for the hardest ones. Running only local leaves capability on the table. Running only cloud sends private data out the door for no reason.
The alternative is routing. A system that decides, per query, where the query should run.
The dial, not the switch
Essay 4 ended with a line: the line between local and cloud is not a wall. It's a dial.
A switch has two positions. A dial has a range. The range is where the interesting engineering lives.
Most production AI today sits at one of two extremes. Either the entire product runs on a local model — private, slow, capped by consumer hardware. Or the entire product runs in the cloud — fast, capable, with every request leaving the user's machine.
Both extremes are simple. Both leave value on the table. The middle position — routing — captures the best of each without inheriting either's weaknesses.
What routing looks like in practice
Three scenarios, three scales.
The developer.
A coding assistant runs locally by default. Autocomplete, small refactors, docstring generation, renames — all local. Code never leaves the laptop. Fast enough, private by default, no per-query cost.
When the developer hits a hard problem — an architecture decision, a bug spanning six services, a subtle race condition — the assistant escalates the query to a cloud model. The developer doesn't press a button. The system decides.
The developer experiences one assistant. Behind the scenes, it's two. The split is based on difficulty, privacy, and latency.
The company.
An internal document search tool runs entirely locally. HR files, legal contracts, financial records, internal memos — none of it leaves the building. The model is small and quantized. It doesn't need to be brilliant. It needs to be accurate and private.
Customer-facing chat runs in the cloud. It needs to be fast, capable, and multilingual. The data flowing through it is public — questions from public users.
Two workloads. Two homes. One product. The company never argues about local versus cloud because it stopped treating them as mutually exclusive.
The person.
A phone assistant handles timers, reminders, quick lookups, and short replies on-device. No network round-trip. No data leaving the phone. Instant, private, available offline.
When the user asks something requiring real reasoning — a multi-day trip plan, a comparison of two products, a debugging session — the query escalates to a cloud model. The user sees one assistant. The phone decided the local model couldn't handle it.
The pattern in all three cases: sensitivity and difficulty decide the route. Private and easy goes local. Public and hard goes to the cloud.
The triangle, revisited
Essay 3 ended with a triangle. Three forces, two of which you can optimize:
- Capacity — how much the model knows
- Latency — how fast it responds
- Memory — how much hardware it needs to run
Local and cloud sit at different points on this triangle.
| Local | Cloud | |
|---|---|---|
| Capacity | Limited by your hardware | Frontier-level |
| Latency | Slow first token, steady after | Fast, but network-dependent |
| Memory | Bounded by your RAM | Effectively unlimited |
Local optimizes memory and privacy, sacrificing capacity. Cloud optimizes capacity and speed, sacrificing privacy and adding dependency.
Routing lets you optimize all three at once — not by building a machine that does everything, but by picking a different point on the triangle for each task. The system is private when privacy matters, capable when capability matters, fast when speed matters. No single machine needs to do all three equally well.
What this means for builders
Three practical takeaways.
Design for two homes.
Any serious AI product in 2026 should have a local path and a cloud path. Not for trend reasons. Because the cost structure, the privacy guarantees, and the latency profile are different for each, and pretending otherwise means leaving value on the table.
Make routing invisible.
Users shouldn't have to choose. The system should decide based on sensitivity, complexity, and latency requirements. A product that asks "would you like to use the local model or the cloud model?" has already failed. That's a question the system answers, not the user.
Measure the dial.
Track how often queries actually need cloud capability. Most products find the number is lower than expected. Sometimes much lower. That gap is money saved, data protected, and latency improved at the same time. The only way to find it is to look.
What this means beyond tech
Three things shift when routing becomes standard.
Access. Local AI lowers the barrier. A capable model doesn't require a subscription. It requires a machine. That's a different kind of democratization — one that doesn't depend on a company's pricing page.
Ownership. When the model runs on your hardware, no one can change the terms. No pricing update, no rate limit, no quiet deprecation. That's a real shift in what it means to have AI. You don't rent it. You have it.
Energy. Local inference is less efficient per token than a hyperscale data center. It's also less total compute when you only use what you need. The energy math is more complex than either side admits, and nobody has fully worked it out yet. Anyone claiming otherwise is selling something.
The closing
The parameter race was never about size. It was about capability, and capability has many shapes.
The local-cloud debate never was about location. It was about trade-offs, and trade-offs have many answers.
The future isn't local. It isn't cloud. It's the system that knows the difference — and chooses well.
New to the jargon? Every term in this guide has a plain-English explanation in the glossary.
About the author
- Father of two, tech lover. Building systems by day, raising curious minds by night. I write hands-on guides and reproducible experiments on running, fine-tuning and evaluating AI locally on Apple Silicon, on AI agents, and on how AI changes software and finance. The code behind every experiment is on GitHub: github.com/hslimi/night-thoughts
Comments
Join the discussionThe 35 GB INT4 example is a useful starting point, but the usable context length deserves its own memory budget. The compressed weights can fit while a longer conversation still runs out of memory because the attention cache and runtime buffers also occupy the same pool. That makes 'the model loads' a weaker test than 'the intended conversation runs.'
For the laptop reality check, I would record memory and response speed at several prompt lengths with the same offload settings. Leaving headroom for the operating system also matters on unified-memory machines. It would make the hardware examples easier to translate into an actual local workload.
Big Models, Small Machines
# Big Models, Small Machines *How local hardware learned to run giant AI — and why size stopped measuring intelligence.* A five-part series on why parameter count stopped measuring intelligence, and how ordinary machines started running extraordinary models. --- ## 📚 Table of Contents | # | Essay | Status | |---|---|---| | 0 | [Plain English Glossary](https://nightthoughts.me/plain-english-glossary-ai-terms-for-the-rest-of-us) | ✅ Published | | 1 | [Bigger Isn't Always Smarter](https://nightthoughts.me/bigger-isn-t-always-smarter) | ✅ Published | | 2 | [How a Laptop Learned to Run a Giant](https://nightthoughts.me/how-a-laptop-learned-to-run-a-giant) | ✅ Published | | 3 | [The New Shape of AI Models](https://nightthoughts.me/the-new-shape-of-ai-models) | ✅ Published | | 4 | [Who Actually Saves Money?](https://nightthoughts.me/who-actually-saves-money) | ✅ Published | | 5 | [The Future Is Both](https://nightthoughts.me/the-future-is-both) | ✅ Published |